Wenxuan Xu 许文轩
I am Wenxuan Xu, an AI Performance Engineer at Elastix AI. I work on LLM inference performance: serving benchmarks, profiling, KV cache behavior, and the tooling that tells us whether a change made inference faster.
I've made some small contributions to SGLang and GuideLLM (vLLM project). I also wrote LiteInfer, a toy inference engine, for practice.
I received my M.S. in Computer Science from Dartmouth College in 2026 and my B.S. from the University of Liverpool / Xi'an Jiaotong-Liverpool University in 2024.
Fun fact: before infra, I did HCI, VR, and LLM-for-health research with Andrew Campbell, Hai-Ning Liang, Wolfgang Stuerzlinger, and Yuntao Wang, and published at ACL, IEEE VR, and ISMAR.
我是许文轩,现在是 Elastix AI 的 AI Performance Engineer,做 LLM inference performance:serving benchmark、profiling、KV cache 行为分析,以及判断一个改动是否真的让推理变快的工具链。
给 SGLang 和 vLLM 项目下的 GuideLLM 做过一些小贡献,也写了 LiteInfer 这个 toy 推理引擎练手。
2026 年在 Dartmouth College 获得计算机科学硕士学位,2024 年在利物浦大学 / 西交利物浦大学获得本科学位。
Fun fact:转 infra 之前,我和 Andrew Campbell、Hai-Ning Liang、Wolfgang Stuerzlinger、Yuntao Wang 做过 HCI、VR 和 LLM 健康方向的研究,在 ACL、IEEE VR 和 ISMAR 发过论文。


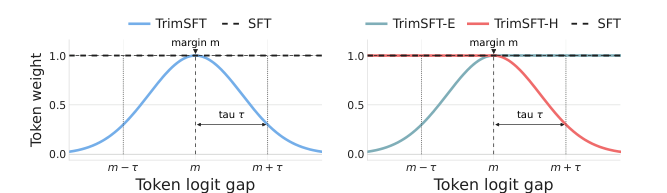
Which Tokens Should SFT Actually Learn? A Token-Trimming Perspective on Mathematical Reasoning
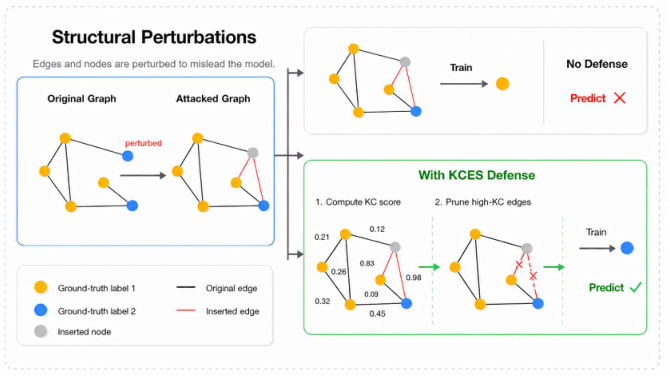


Optimizing Moving Target Selection in VR by Integrating Proximity-Based Feedback Types and Modalities

Exploring the Effects of Spatial Constraints and Curvature for 3D Piloting in Virtual Environments